HPCG SpMV Optimization
Four independent accumulators, one sparse kernel. Inspect the implementation, compare the original timings, and reproduce the correctness checks.
Live Links
| What | Link |
|---|---|
| Repository | https://github.com/rohaan2802/SPMV_Optimization |
| GitHub Pages | https://rohaan2802.github.io/SPMV_Optimization/ |
| Benchmark comparison CSV | https://rohaan2802.github.io/SPMV_Optimization/results/comparison.csv |
Contents
Overview
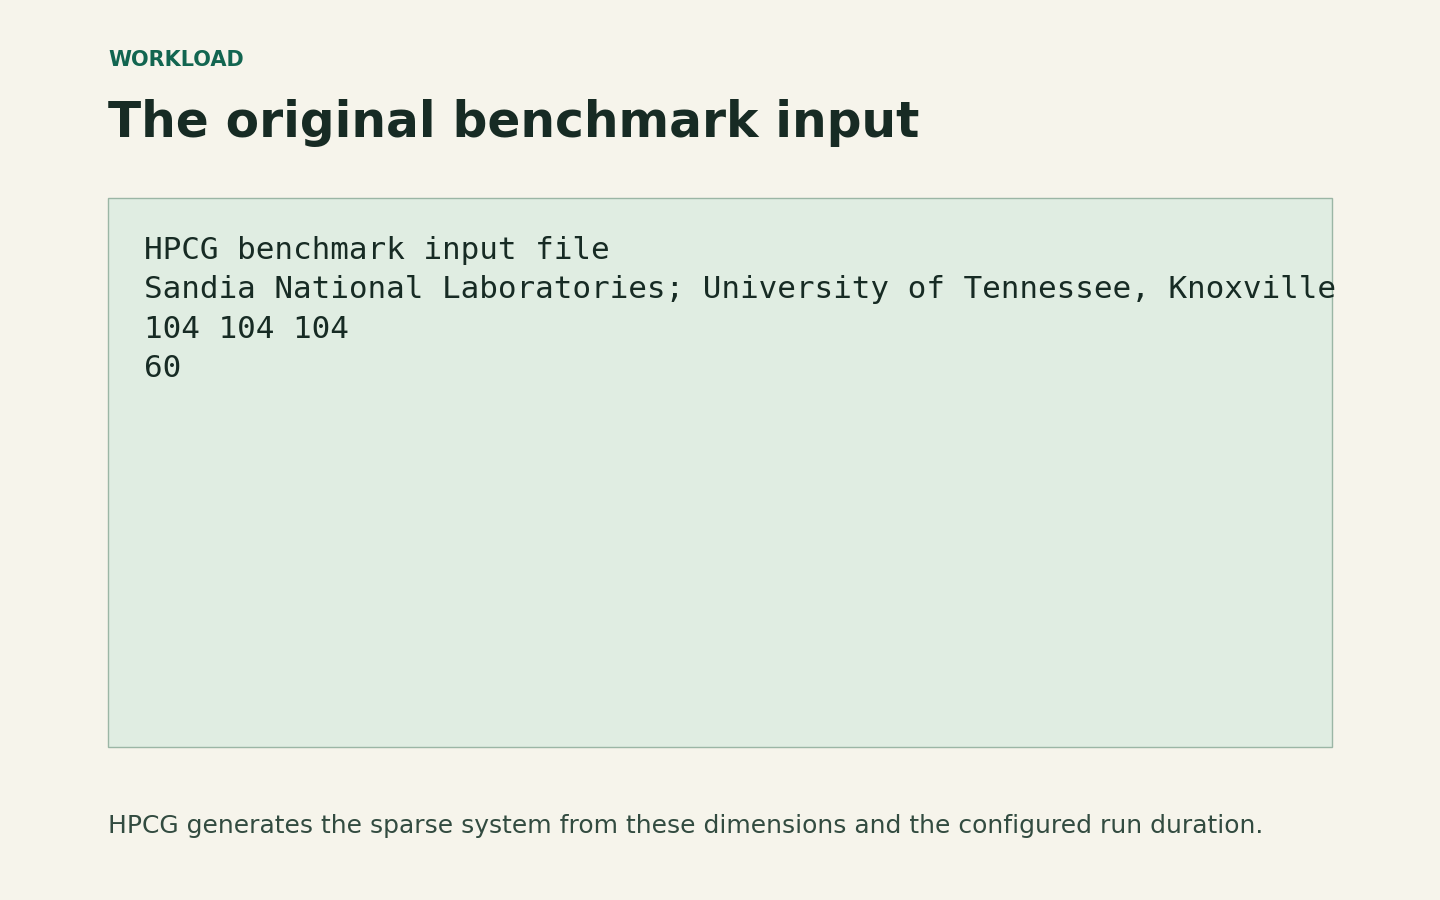
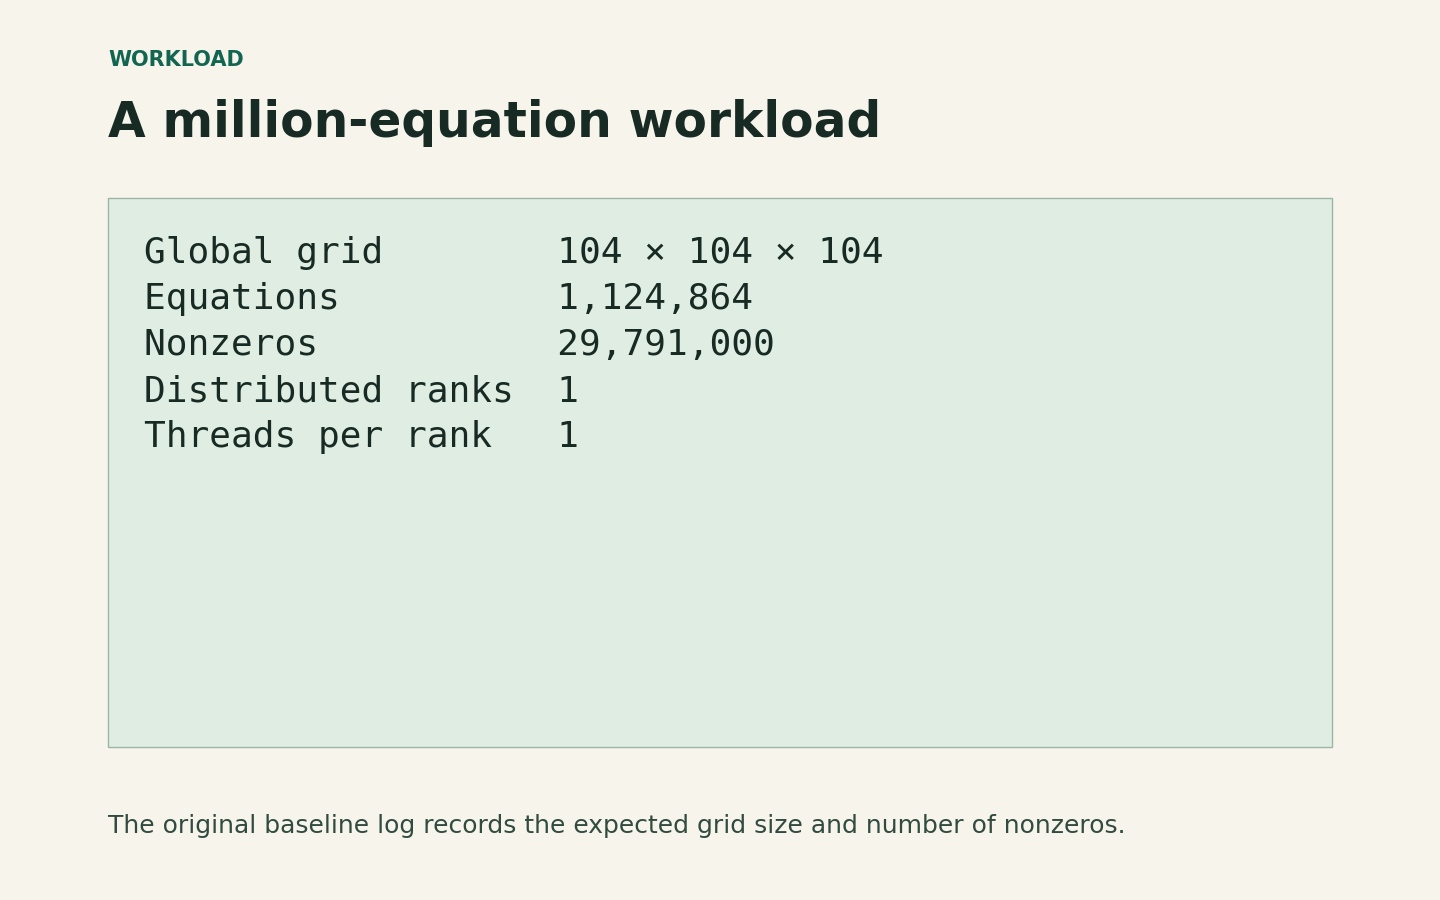
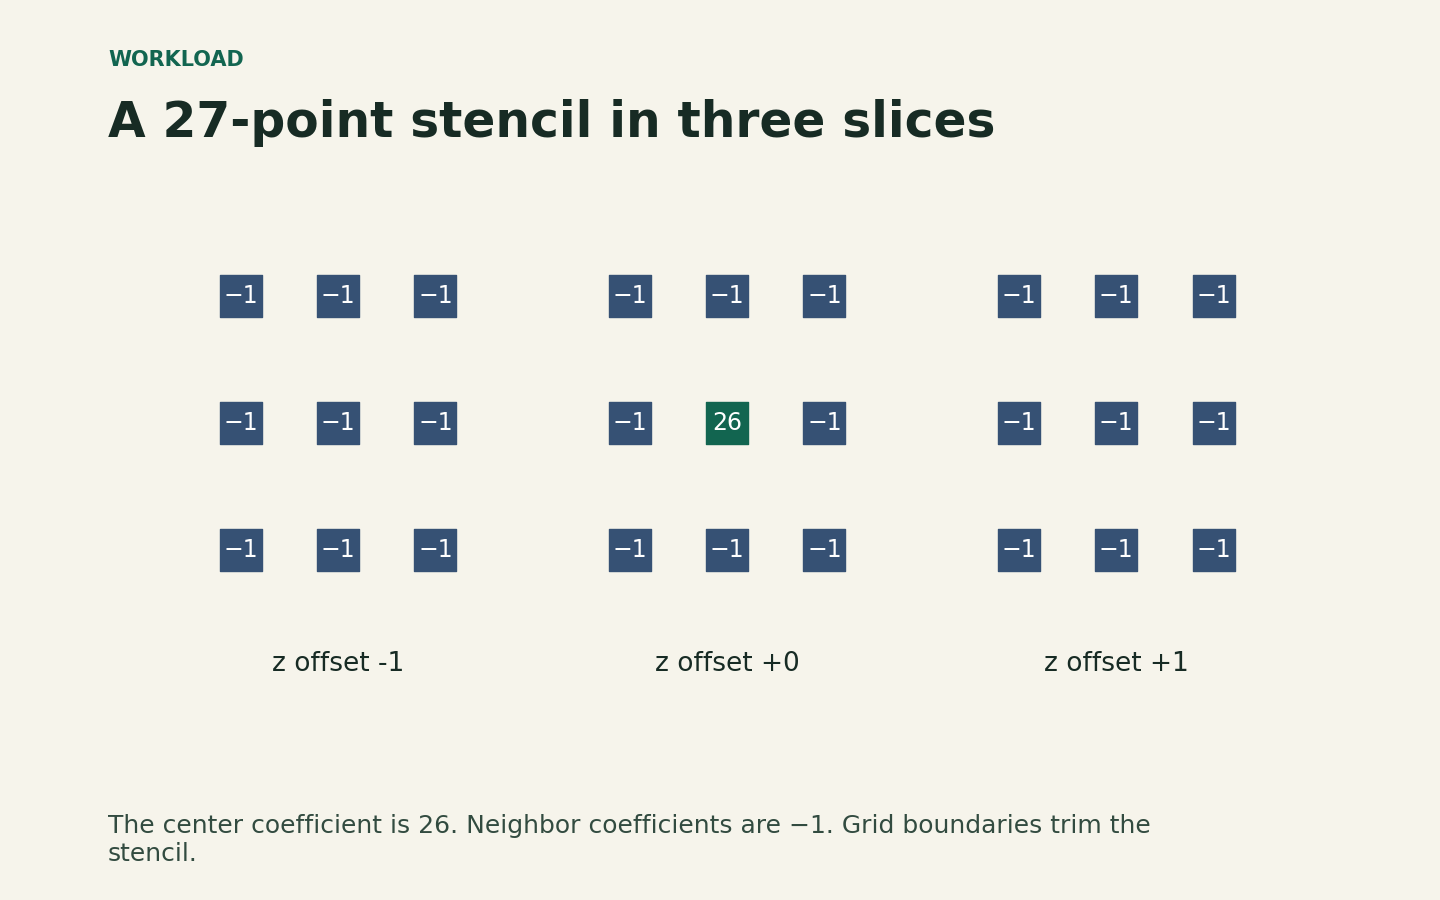
This CS-2008 Numerical Computing project evaluates four-way loop unrolling in the sparse matrix–vector multiplication (SpMV) kernel of HPCG 3.1. Each row calculates one dot product y[i] from the stored coefficients and the corresponding entries of x. HPCG generates a sparse linear system from a three-dimensional 27-point stencil. The original input uses a 104 × 104 × 104 grid, producing 1,124,864 equations and 29,791,000 nonzeros. The input file defines the dataset, so no external matrix download is required.
Interactive Stencil Demo
Choose a position in the grid and an input vector. Each included cell shows one coefficient multiplied by its input value. The demo evaluates that sparse row using both accumulation orders.
The demo calculates a single row in the browser. The C++ executables generate the full sparse system and run the solver.
What’s Inside
| File | Purpose |
|---|---|
| src/compute_spmv_unrolled.cpp | Maintained four-accumulator kernel |
| third_party/hpcg/src/ComputeSPMV_ref.cpp | Independent upstream reference |
| data/hpcg.dat | Original 104 × 104 × 104 input and 60-second target |
| results/comparison.csv | Five metrics extracted from the two original logs |
| results/original/HPCG-Benchmark_3.1_2025-12-07_19-41-10.txt | Original baseline run |
| results/original/HPCG-Benchmark_3.1_2025-12-07_20-49-54.txt | Original unrolled run |
| results/local_checks/baseline_16cube.txt | Current baseline validity check |
| results/local_checks/unrolled_16cube.txt | Current unrolled validity check |
| tests/spmv_test.cpp | Row equivalence check across all HPCG row lengths |
| docs/full_report.pdf | Project methodology and discussion |
| docs/summary_report.pdf | Short project report |
| docs/presentation.pptx | Original presentation deck |
| archive/README.md | Submitted patch, earlier runs, and audit notes |
Project Breakdown
Workload and memory access
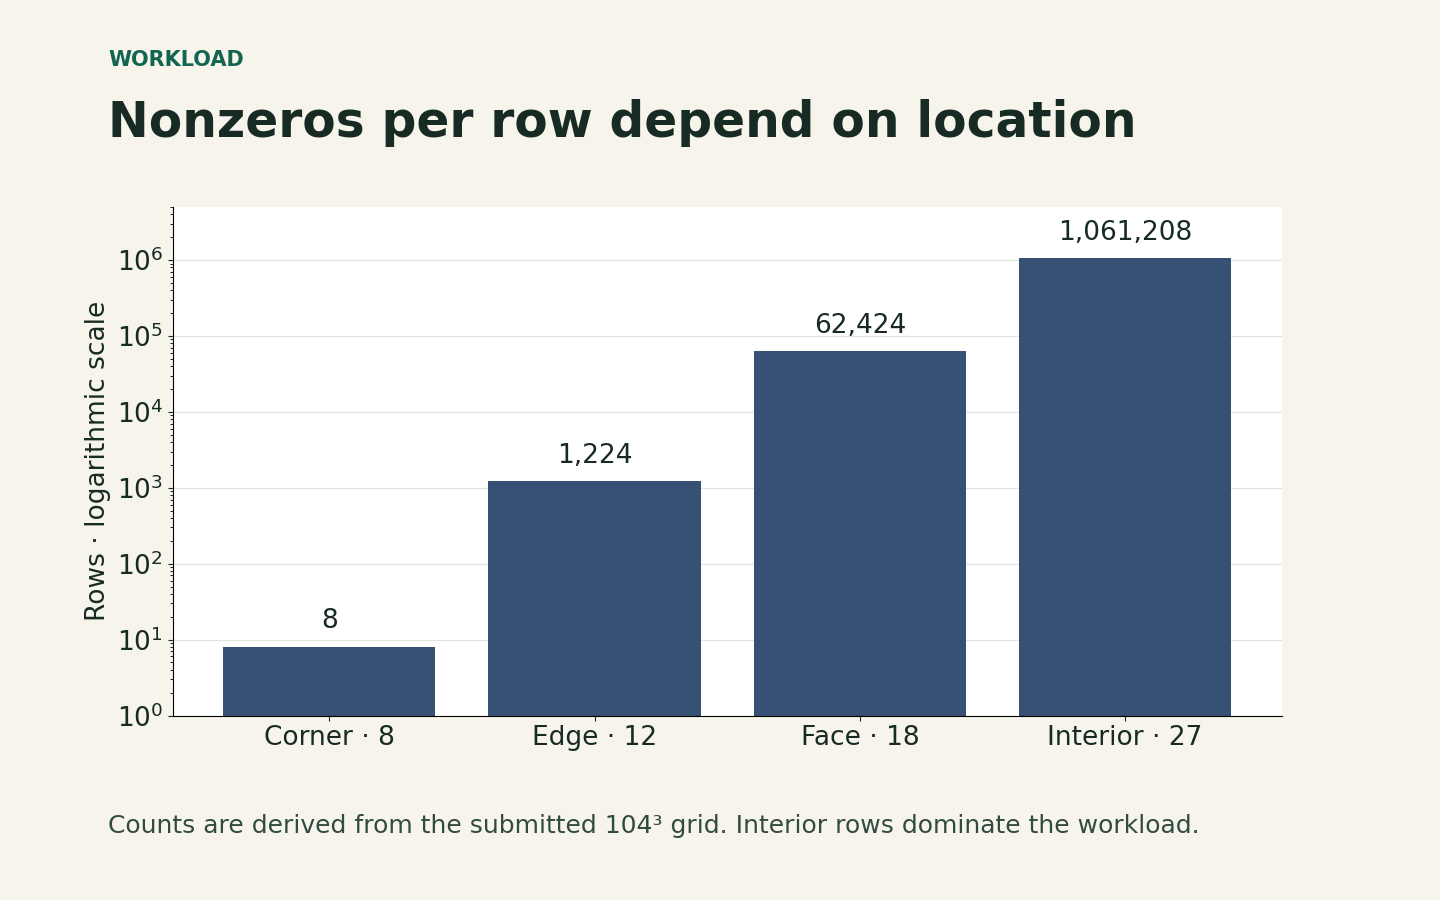
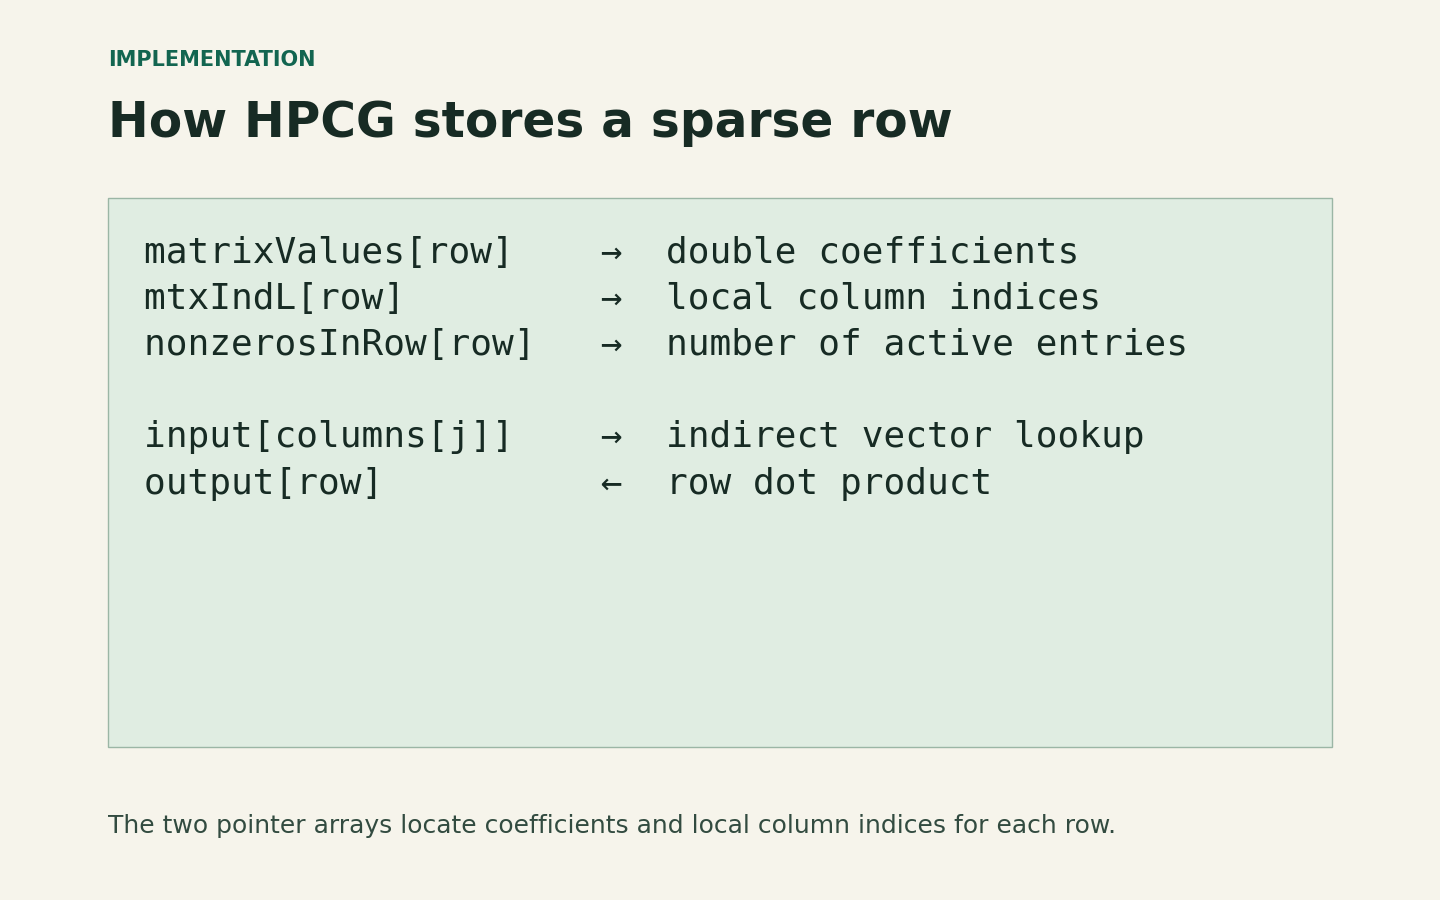
HPCG stores a pointer to each row’s coefficients, a pointer to its local column indices, and a count of the active entries. Boundary rows have 8, 12, or 18 entries. Interior rows have 27. The inner loop performs indirect reads from x, and work is proportional to the number of nonzeros.
Four-way unrolling and reduction
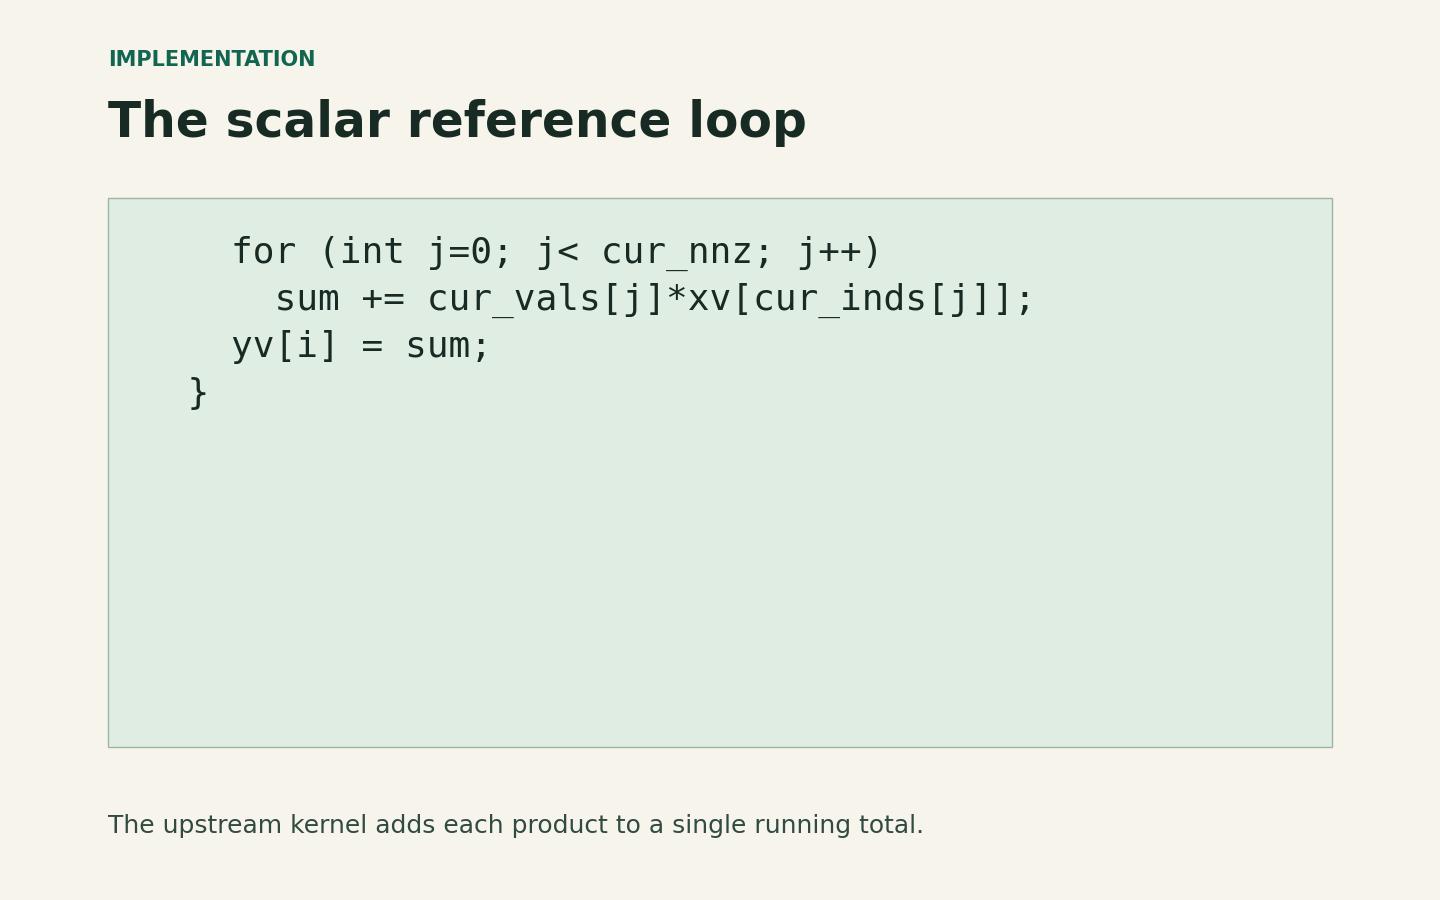
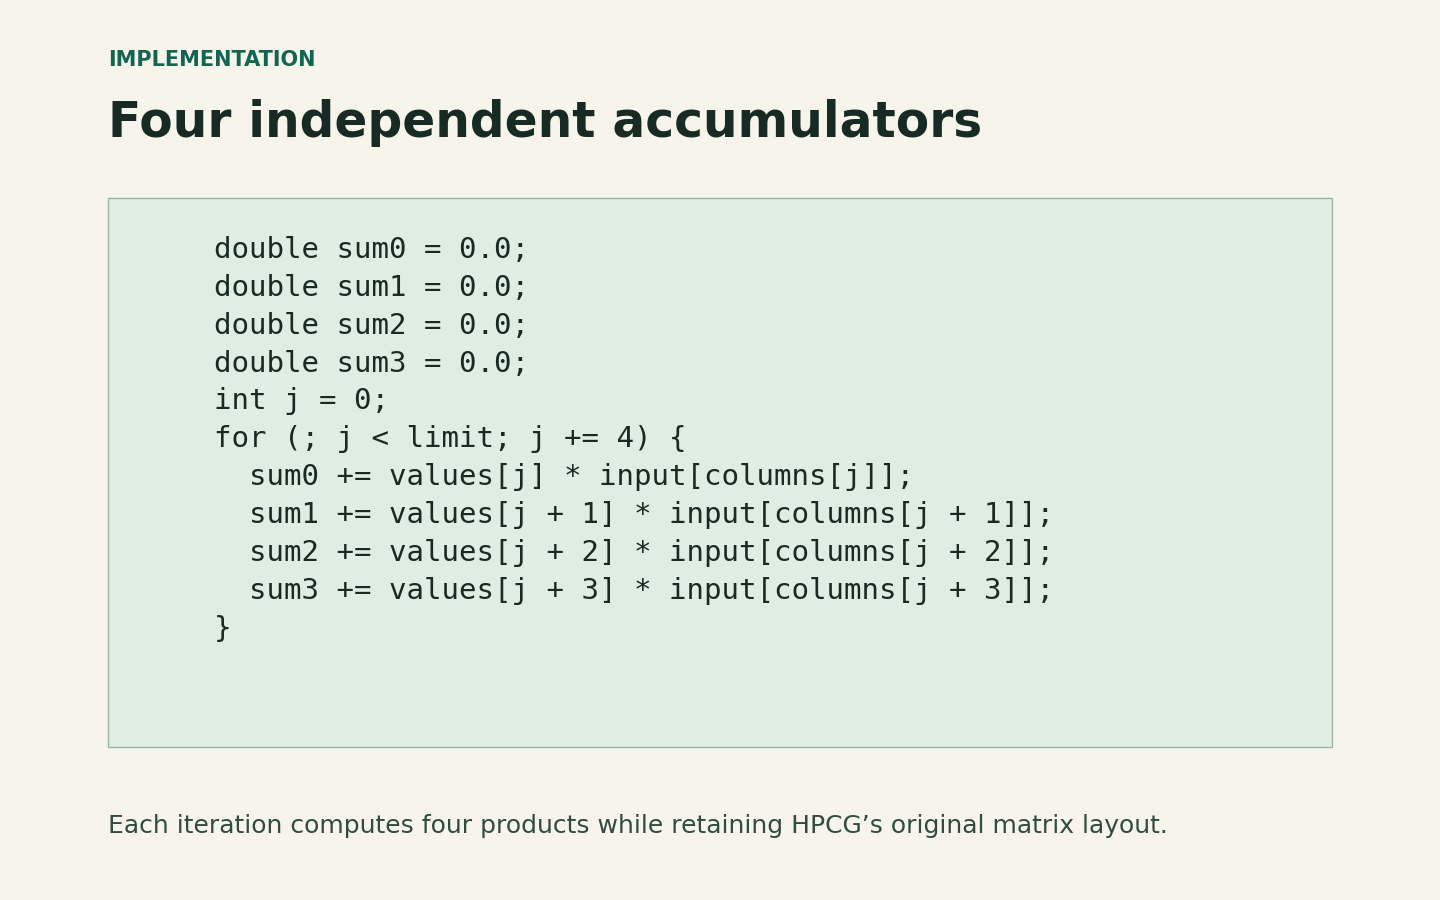
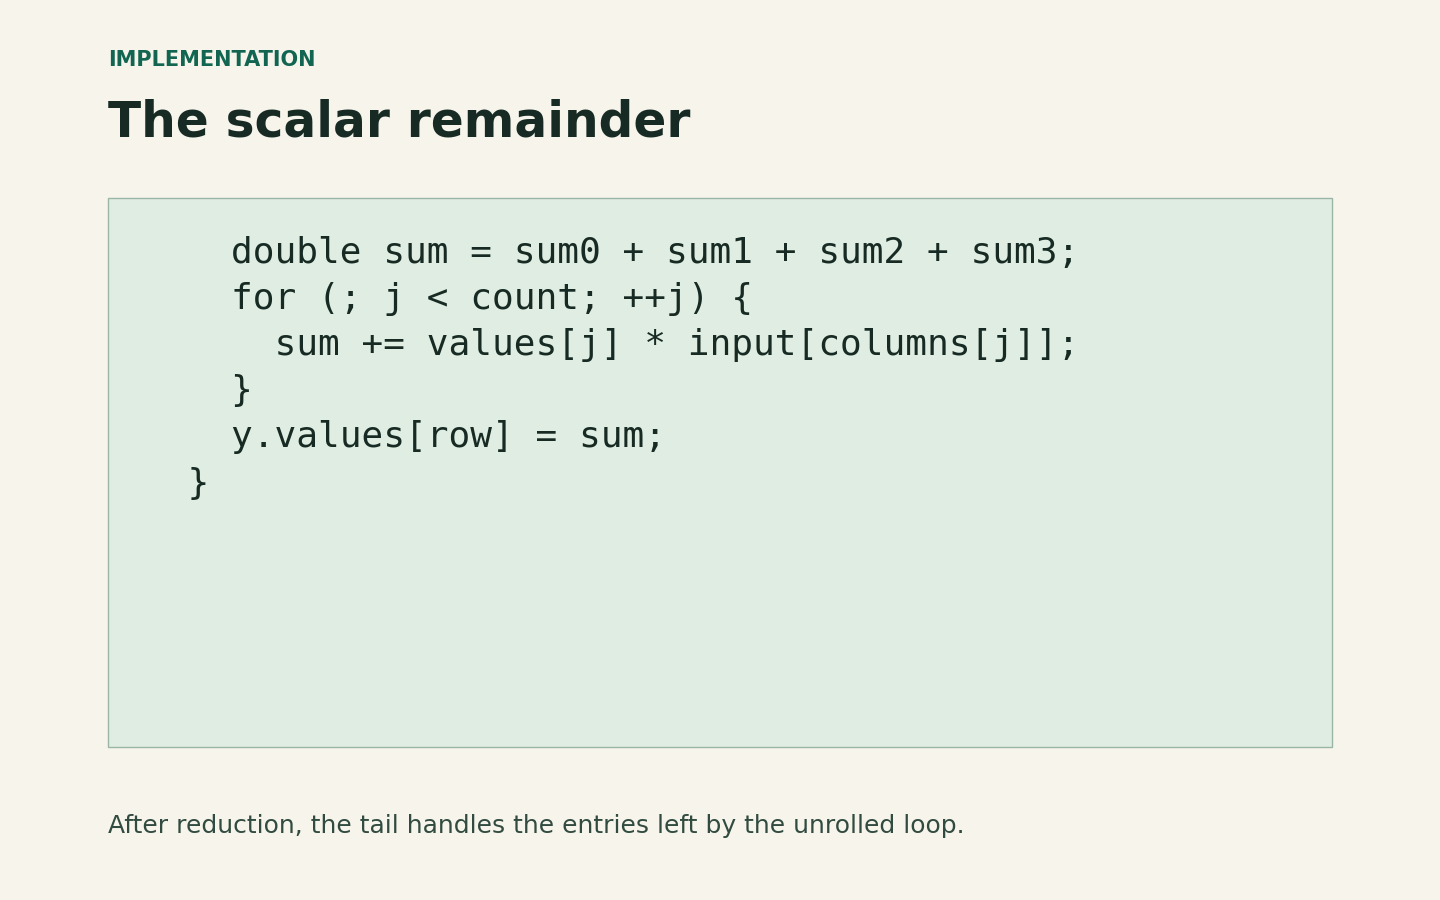
The scalar loop accumulates into one running total. The optimized loop processes four entries per iteration with four separate partial sums. It then combines those sums and handles the last zero to three entries with a scalar loop. The matrix layout and the number of products remain the same. The changed addition order can introduce small floating-point differences.
Integration and provenance
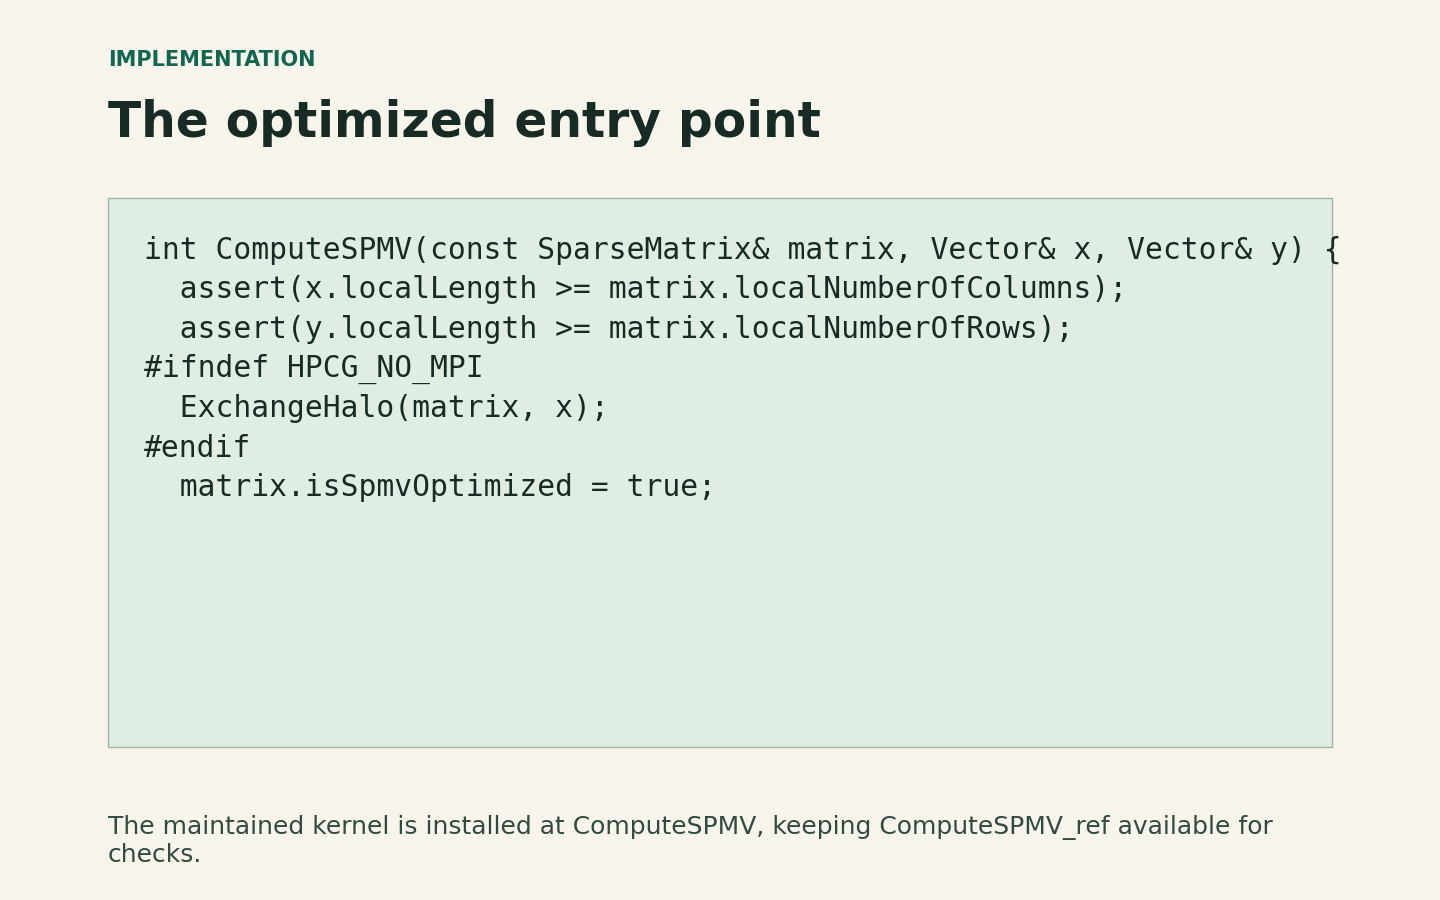
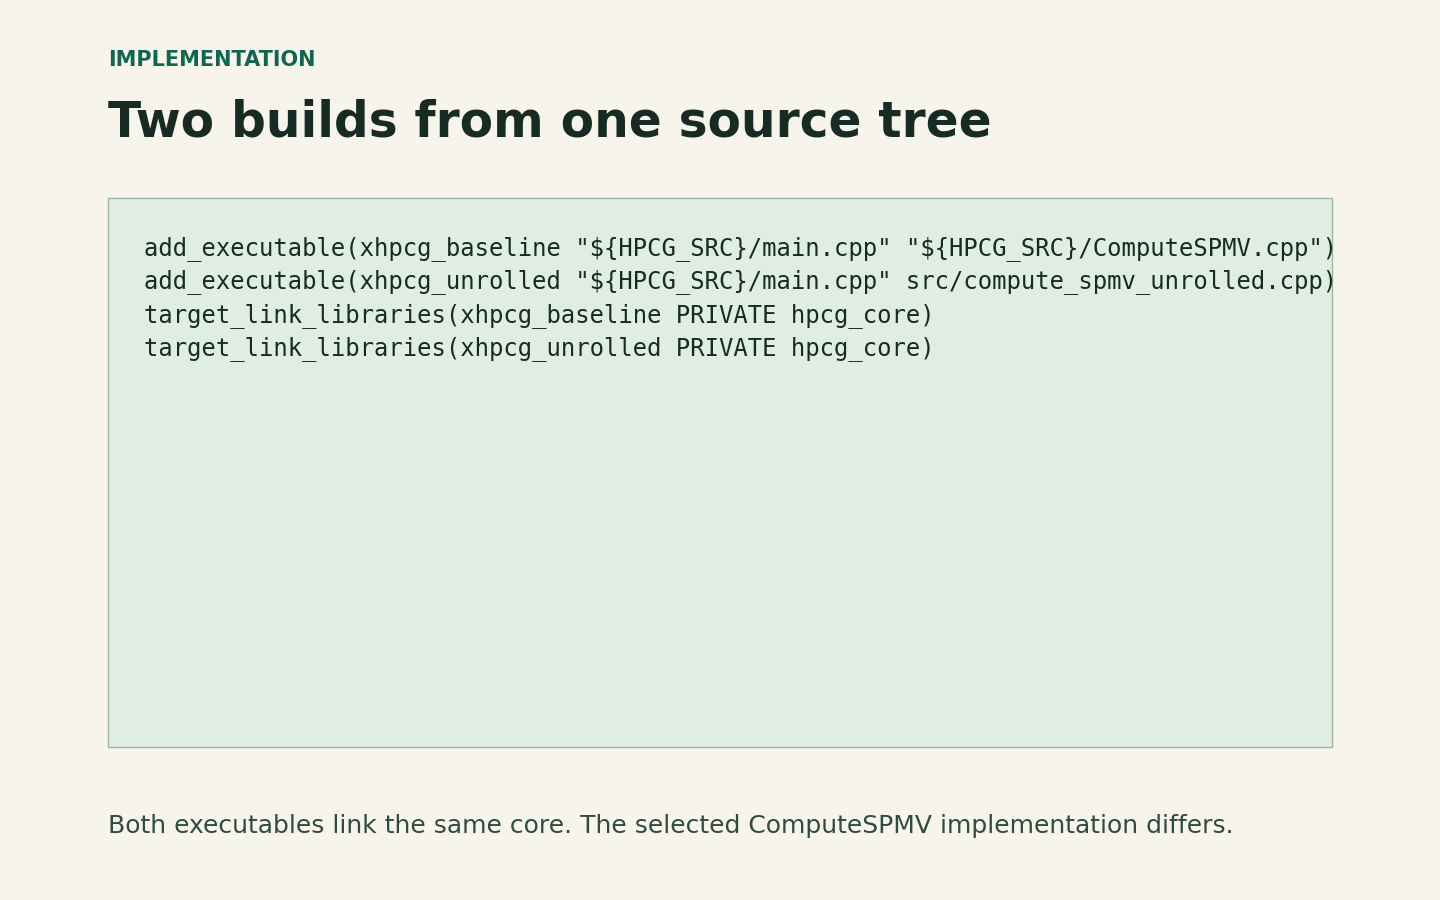
The maintained build selects the implementation at ComputeSPMV and keeps the upstream ComputeSPMV_ref intact. This preserves an independent scalar reference for HPCG's internal checks. The original submission changed ComputeSPMV_ref itself, and that version is archived. The technique was inspired by research on vectorizing SpMV. It uses scalar source operations and makes no assumption about which SIMD instructions a compiler emits.
Folder Structure
SPMV_Optimization/
├── CMakeLists.txt           Baseline, unrolled, and CTest targets
├── src/                     Maintained kernel and portable timer
├── third_party/hpcg/        Pinned reference benchmark and notices
├── tests/                   Direct kernel comparison
├── data/                    Original workload specification
├── results/                 Original logs, comparison, local checks
├── docs/                    Reports, assignment, and slides
├── archive/                 Submitted source and earlier experiments
├── tools/                   Figure and results extraction
├── assets/                  Site code and screenshot gallery
└── index.html               GitHub Pages entry point
Setup
Use CMake 3.16 or newer, Ninja and a C++17 compiler. The commands build single-rank, single-thread Release executables. On Windows use a configured C++ toolchain, such as MSYS2 UCRT64 GCC with its bin directory on PATH. On Linux or WSL use GCC or Clang.
cmake -S . -B build -G Ninja -DCMAKE_BUILD_TYPE=Release
cmake --build build
ctest --test-dir build --output-on-failure
Linux or WSL smoke runs
# Linux or WSL, from the repository root
mkdir -p run/baseline run/unrolled
(cd run/baseline && ../../build/xhpcg_baseline --nx=16 --ny=16 --nz=16 --rt=1)
(cd run/unrolled && ../../build/xhpcg_unrolled --nx=16 --ny=16 --nz=16 --rt=1)
PowerShell smoke runs
# PowerShell, from the repository root
New-Item -ItemType Directory -Force run/baseline,run/unrolled | Out-Null
Push-Location run/baseline
& ../../build/xhpcg_baseline.exe --nx=16 --ny=16 --nz=16 --rt=1
Pop-Location
Push-Location run/unrolled
& ../../build/xhpcg_unrolled.exe --nx=16 --ny=16 --nz=16 --rt=1
Pop-Location
For the original workload, copy data/hpcg.dat into each run directory and invoke the same executable there without flags. Keep runs in separate directories to retain both logs. Use the 16³ case first for a quick check.
Results
Original 104³ benchmark
| Metric | Baseline | Unrolled | Change |
|---|---|---|---|
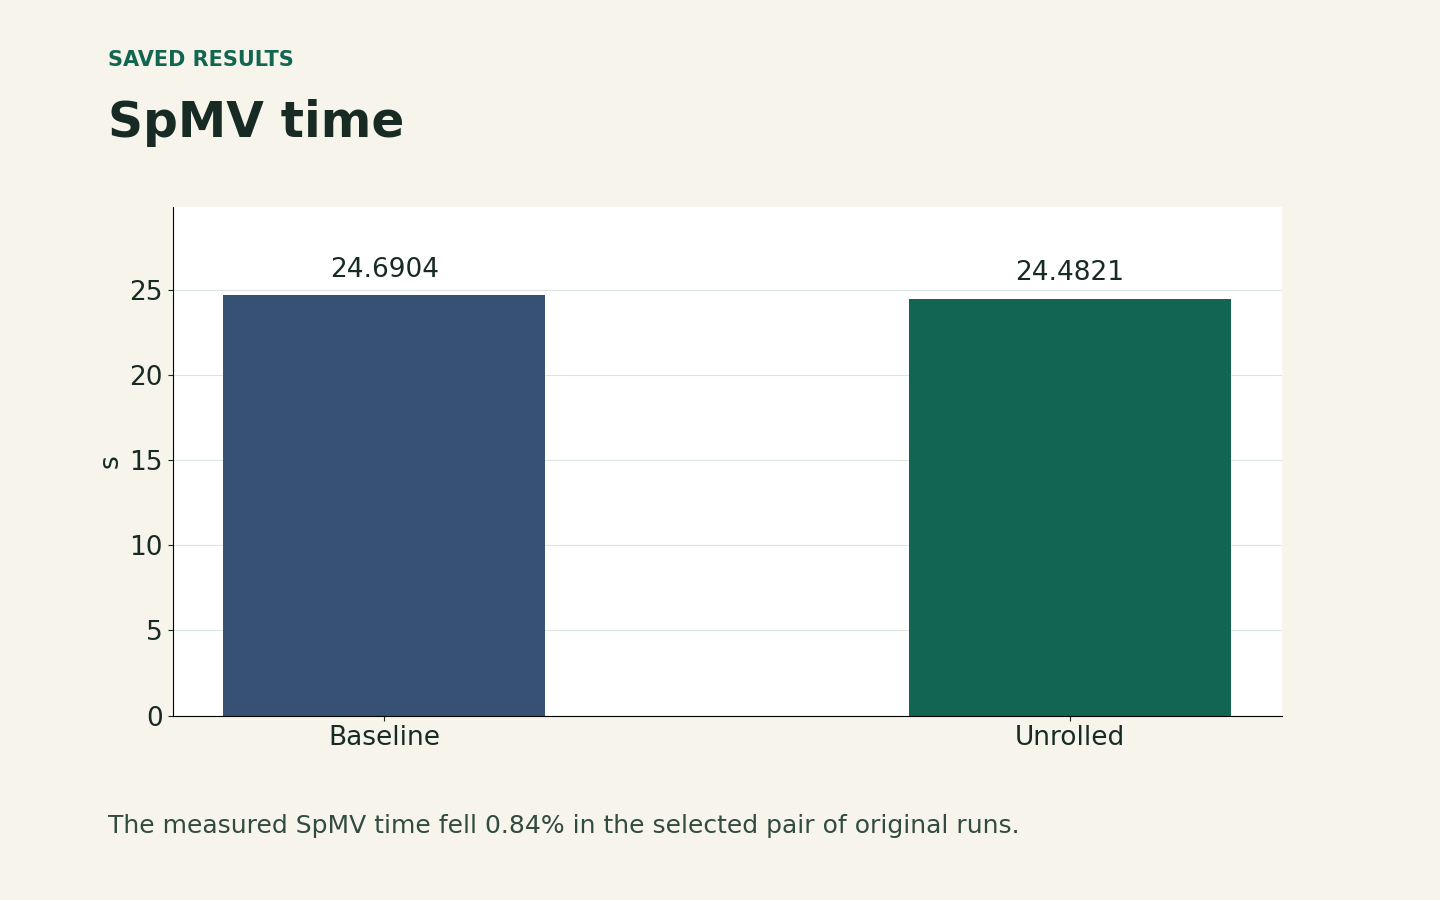
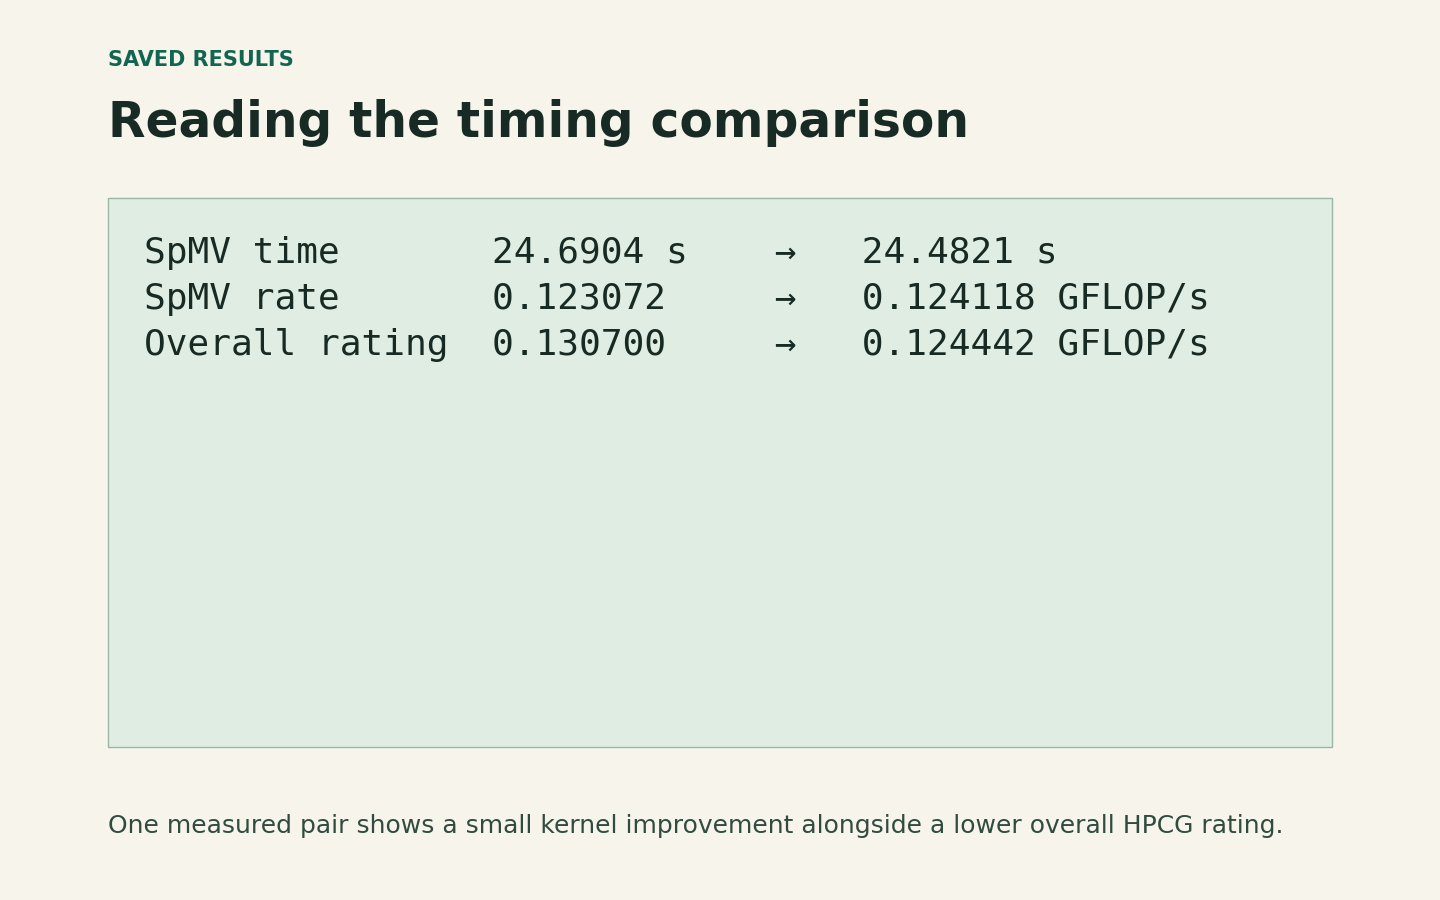
| SpMV time | 24.6904 s | 24.4821 s | −0.84% |
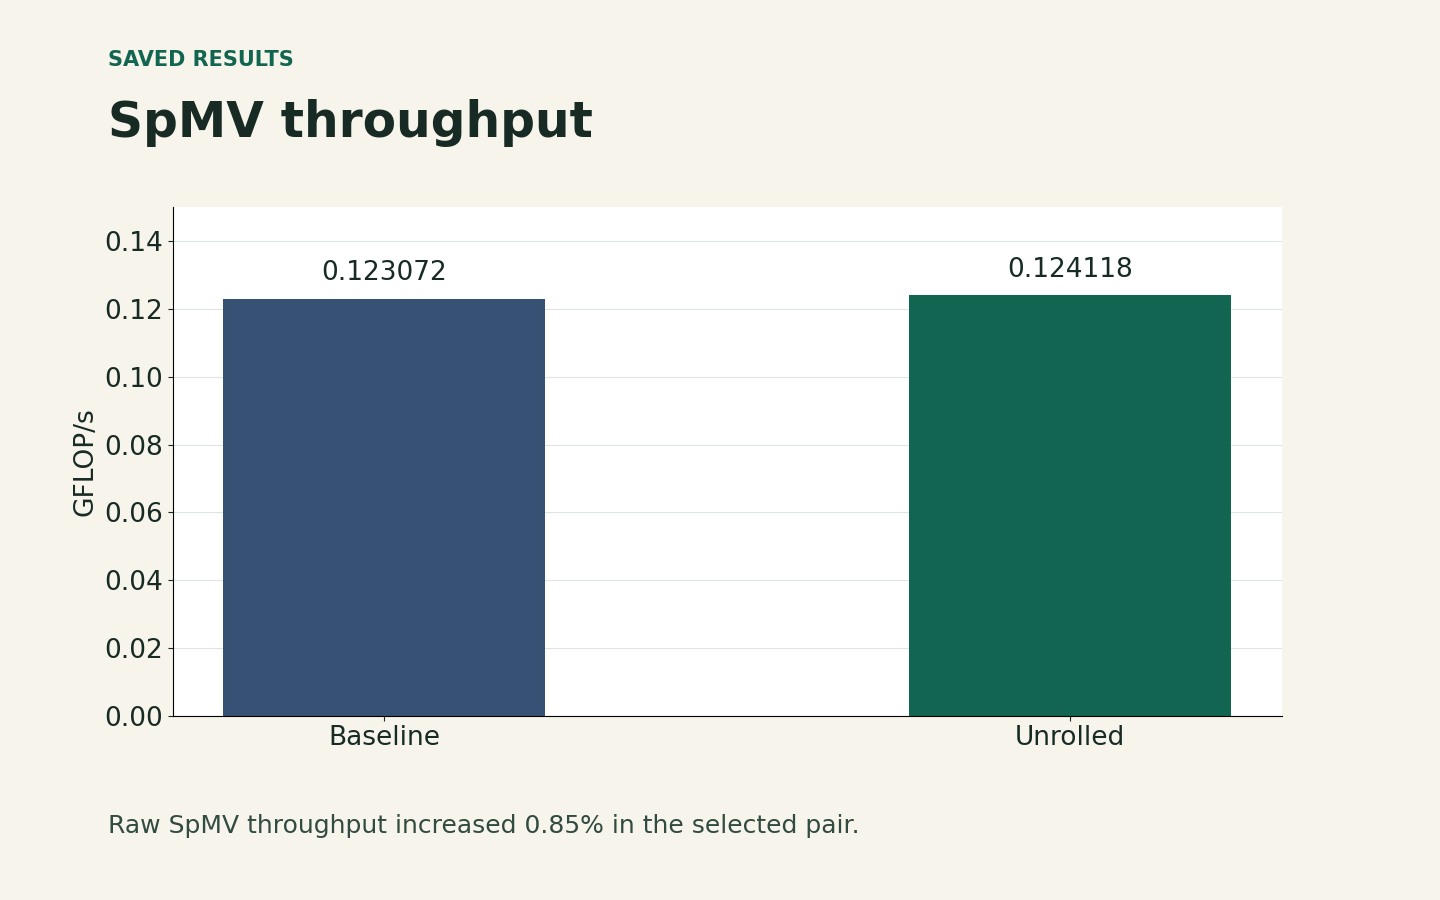
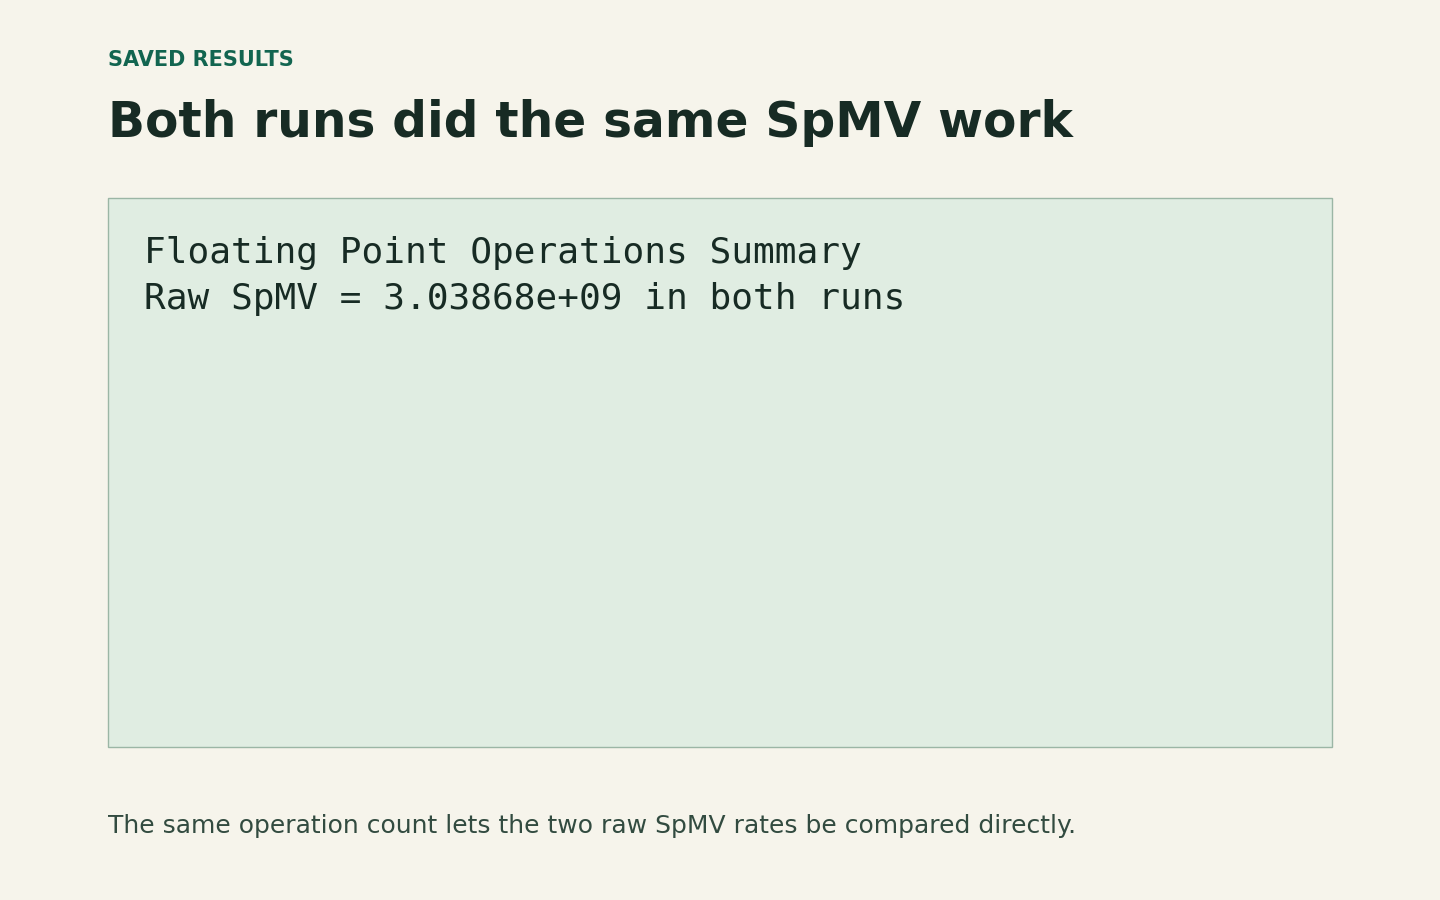
| Raw SpMV rate | 0.123072 GFLOP/s | 0.124118 GFLOP/s | +0.85% |
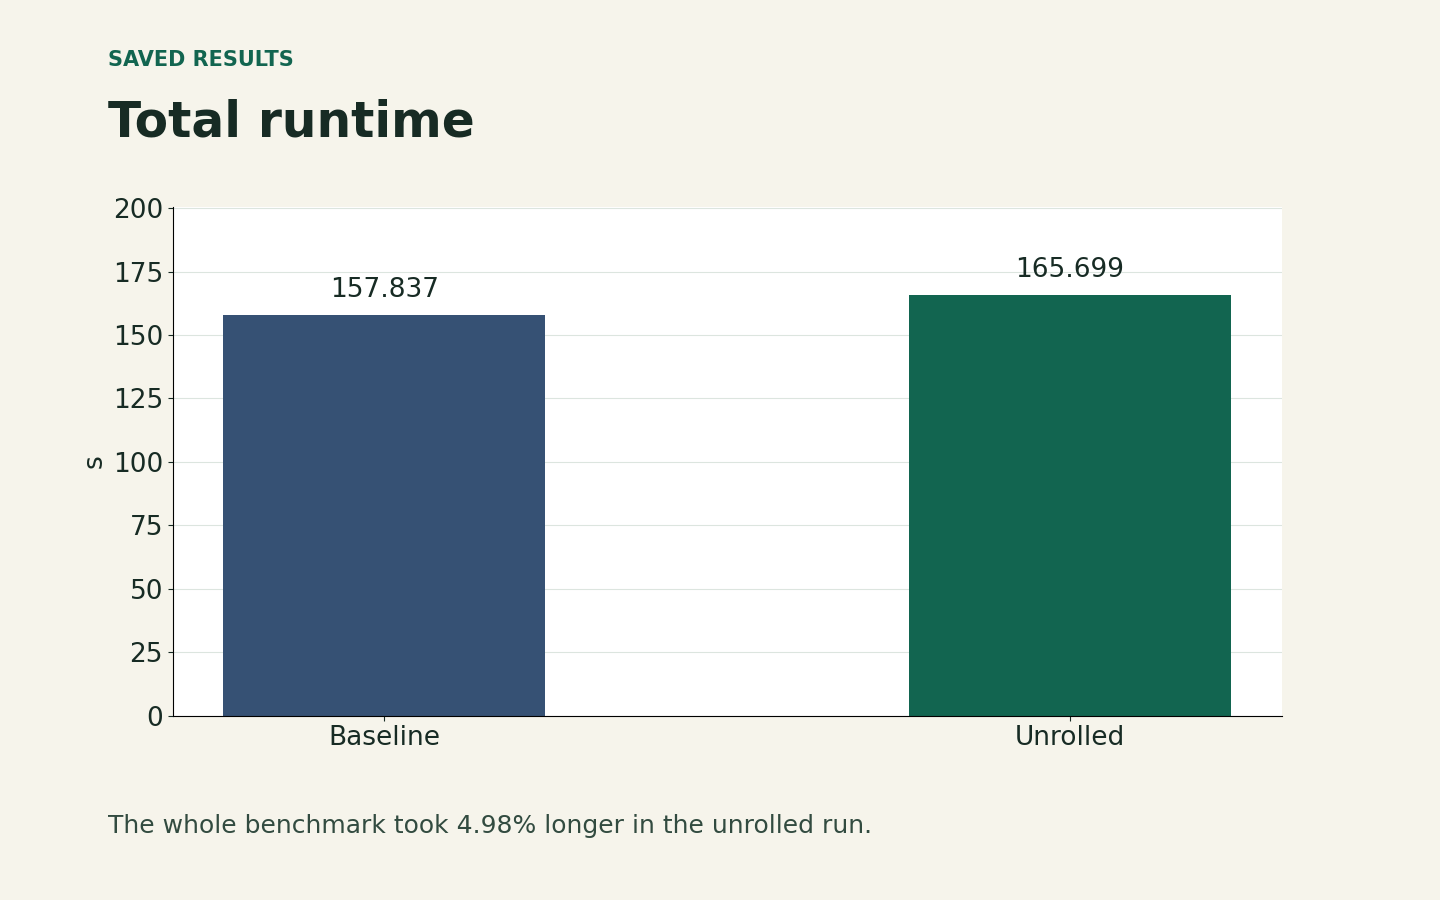
| Total runtime | 157.837 s | 165.699 s | +4.98% |
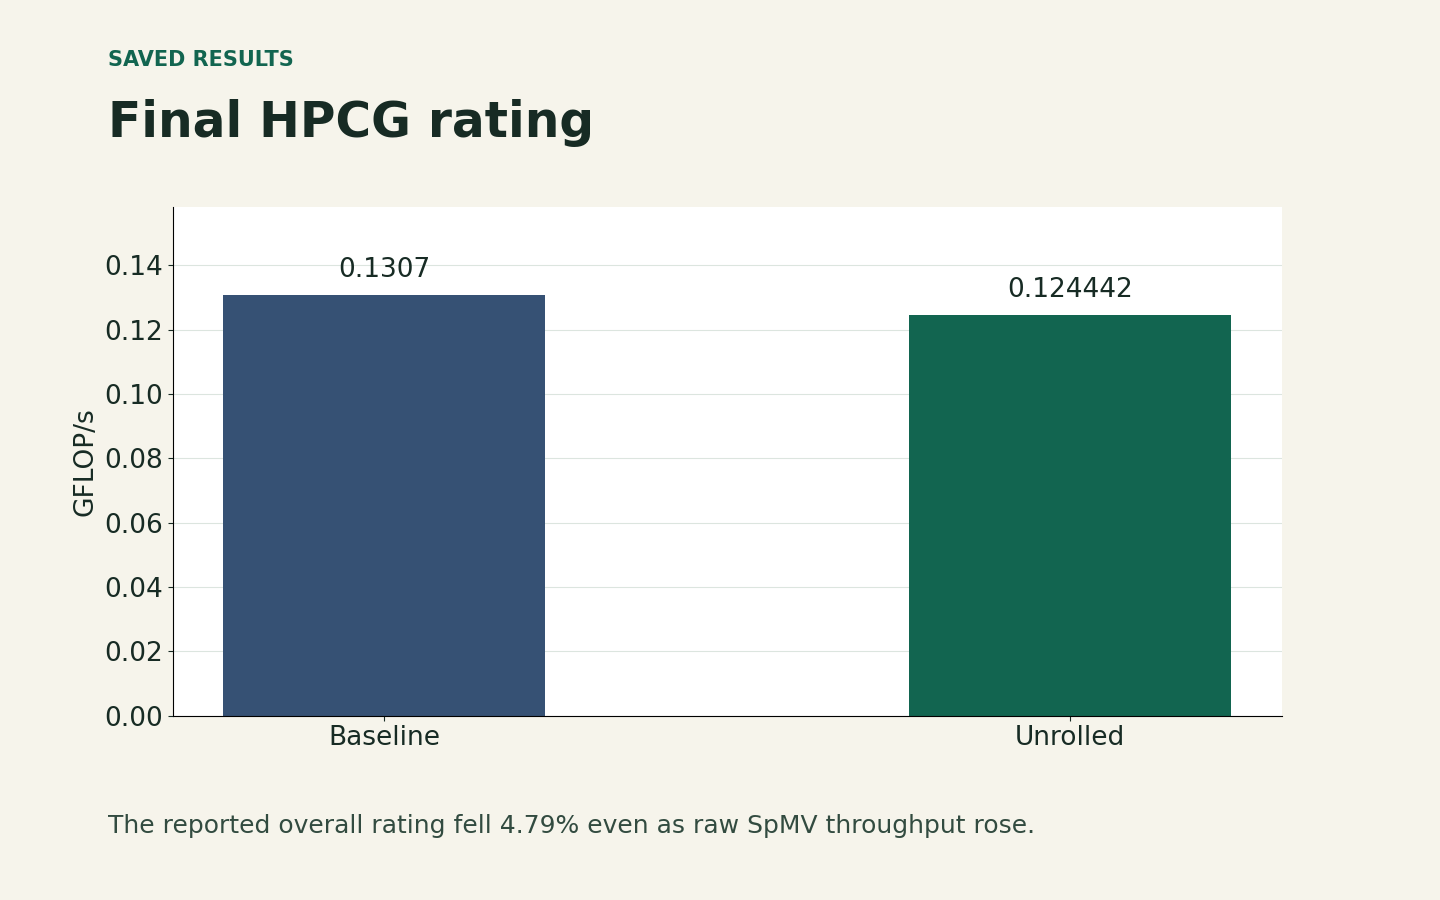
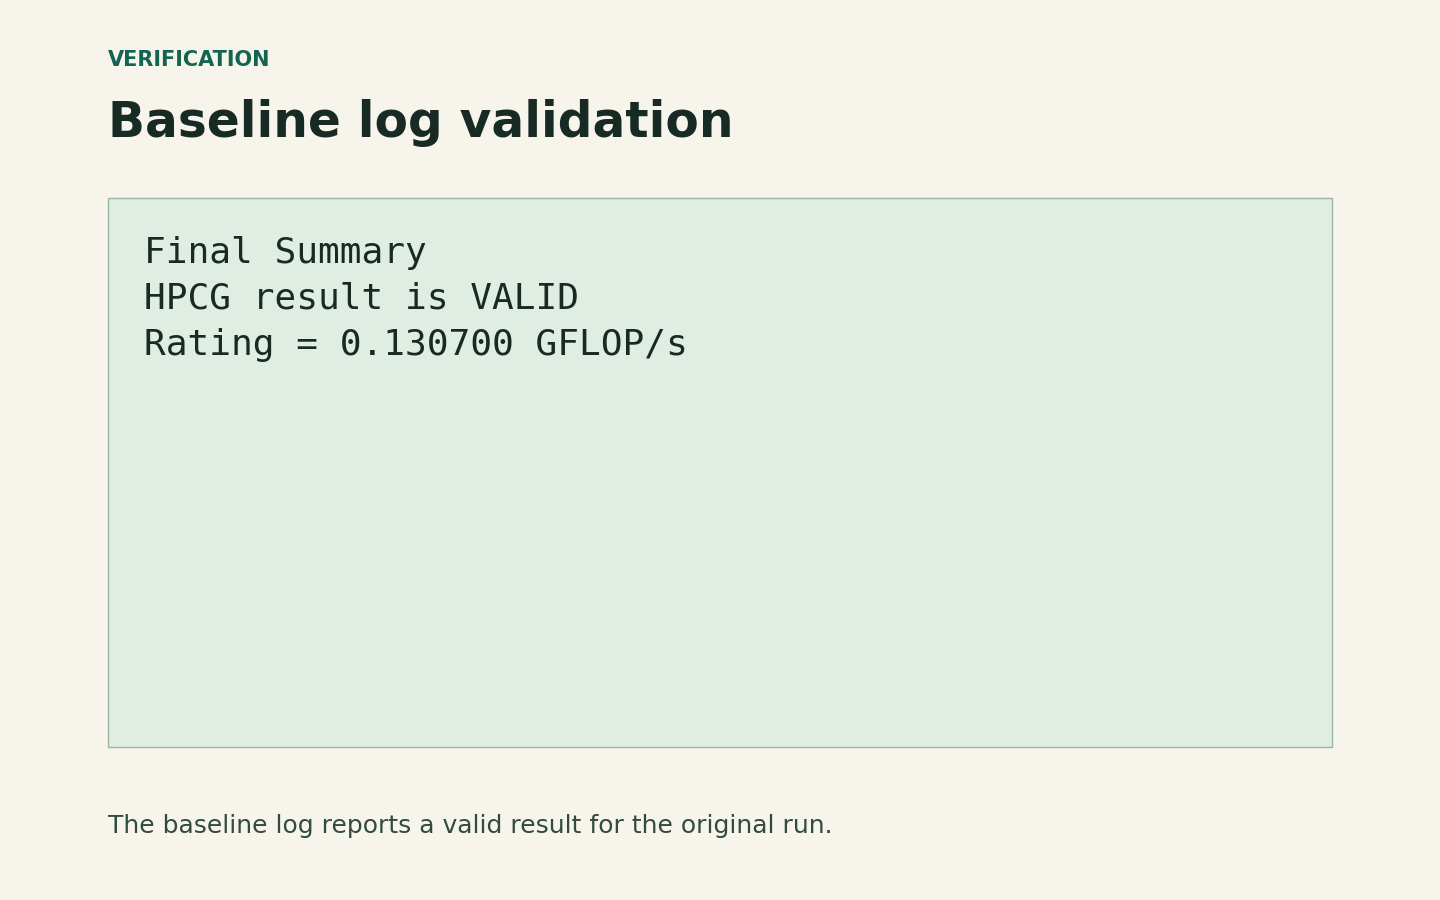
| Final HPCG rating | 0.130700 GFLOP/s | 0.124442 GFLOP/s | −4.79% |
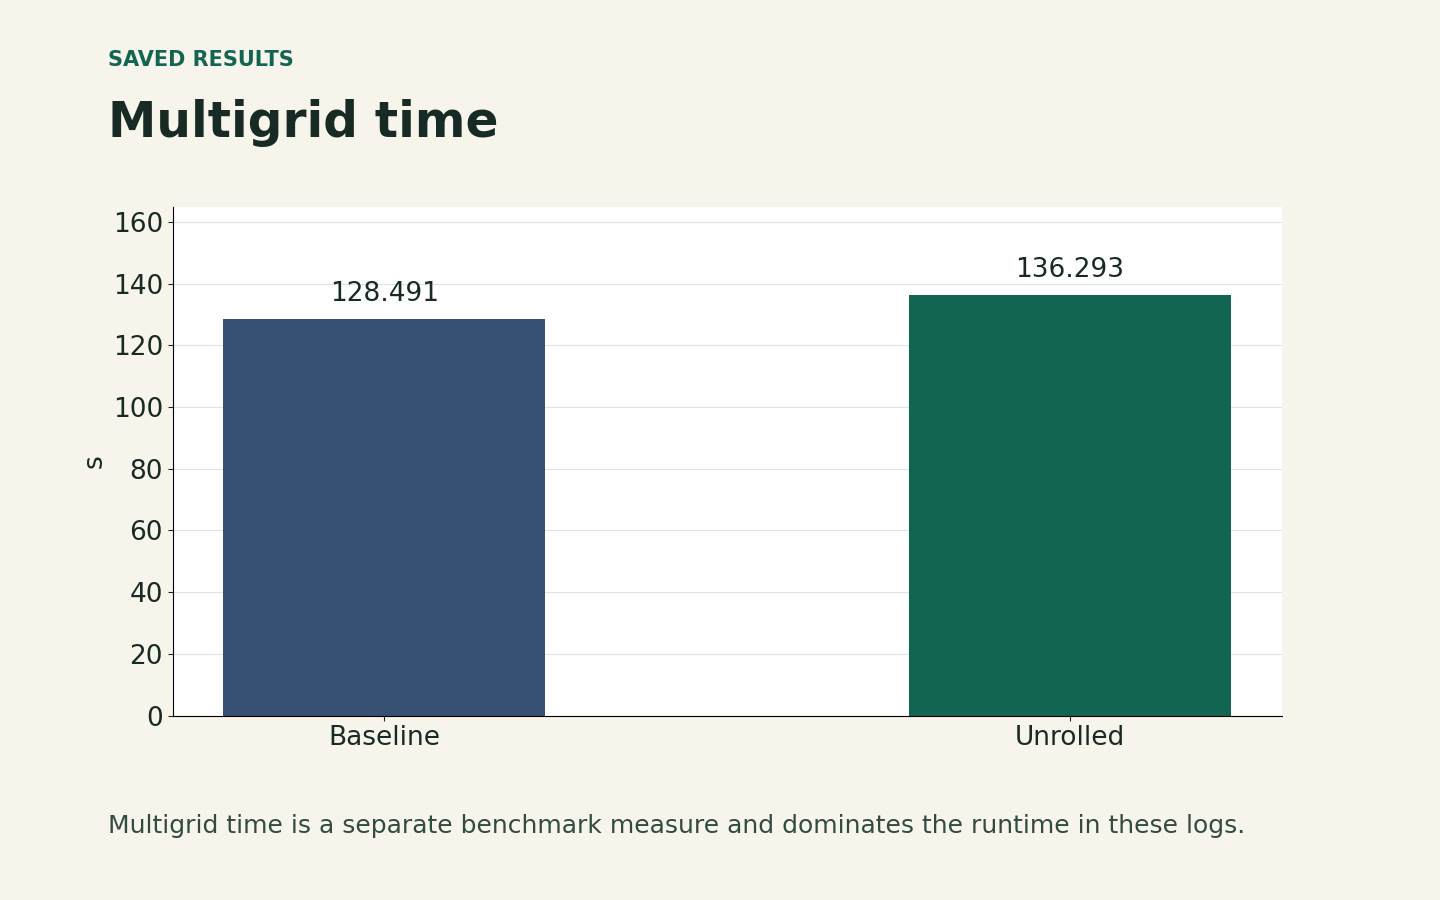
| Multigrid time | 128.491 s | 136.293 s | +6.07% |
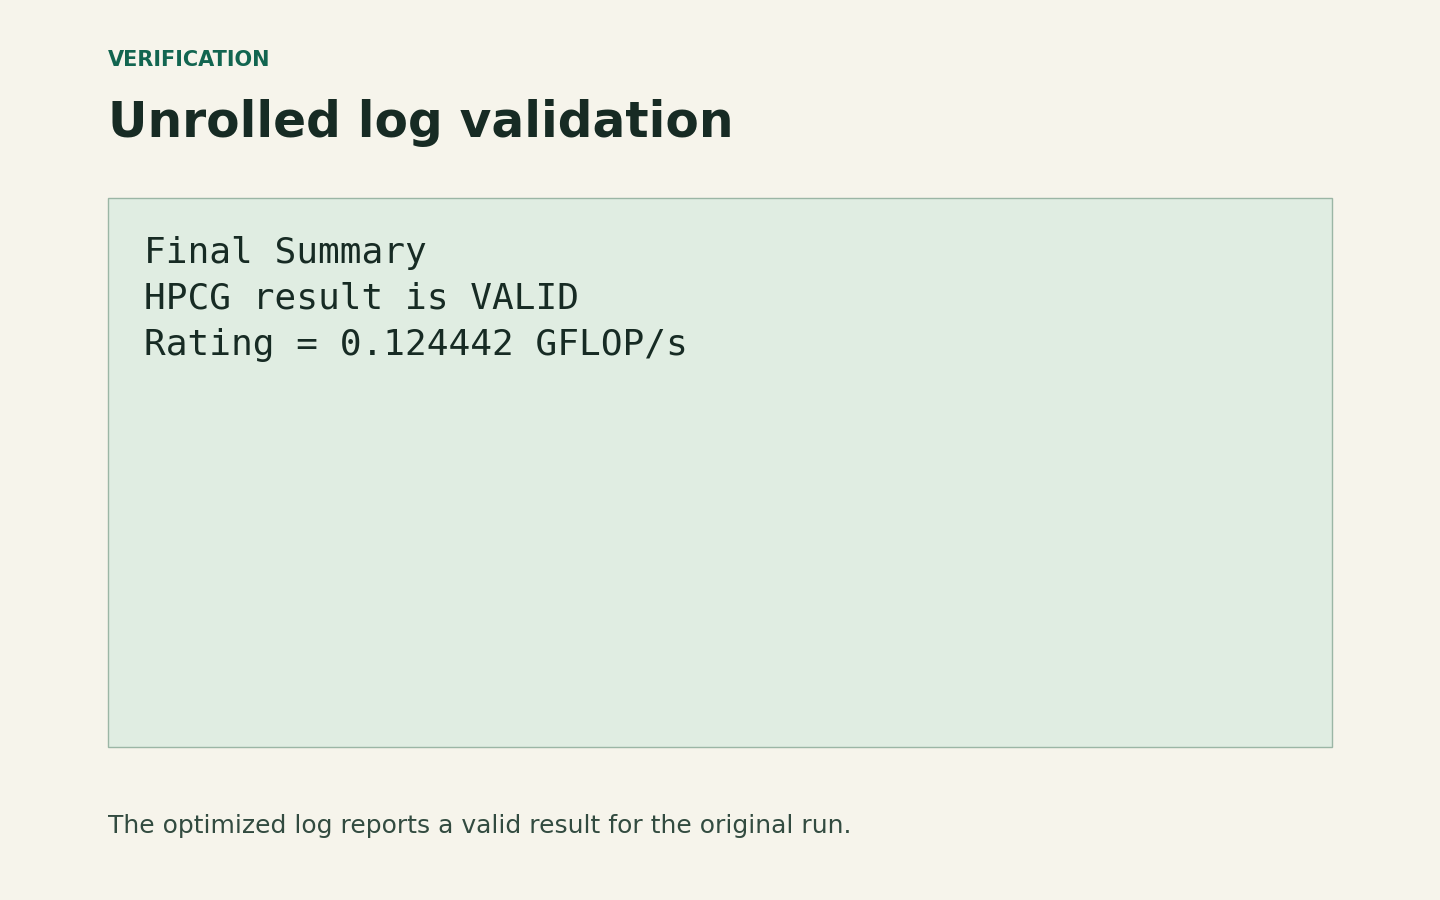
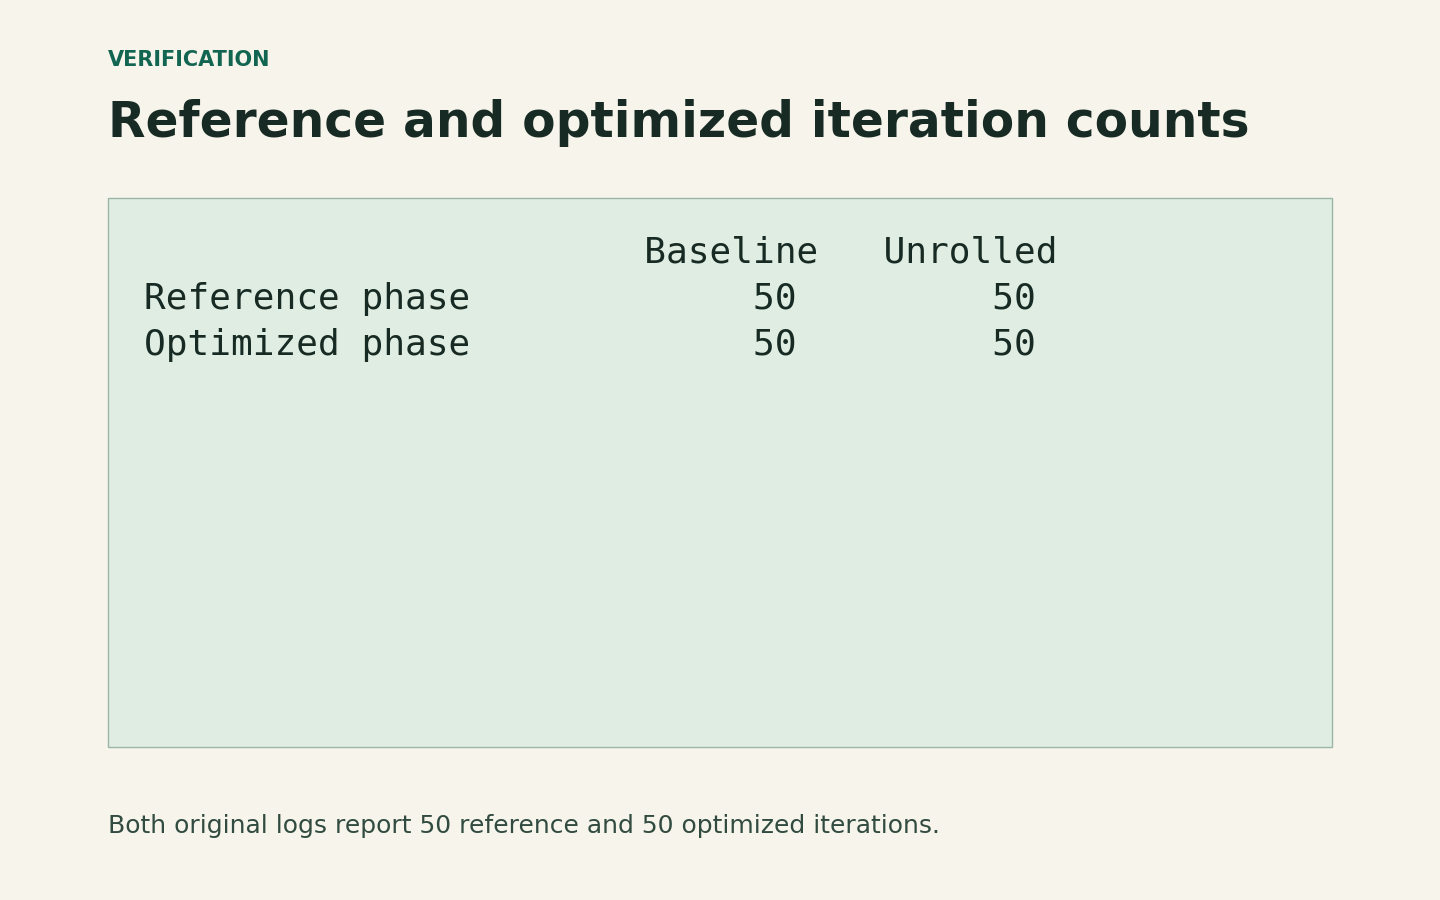
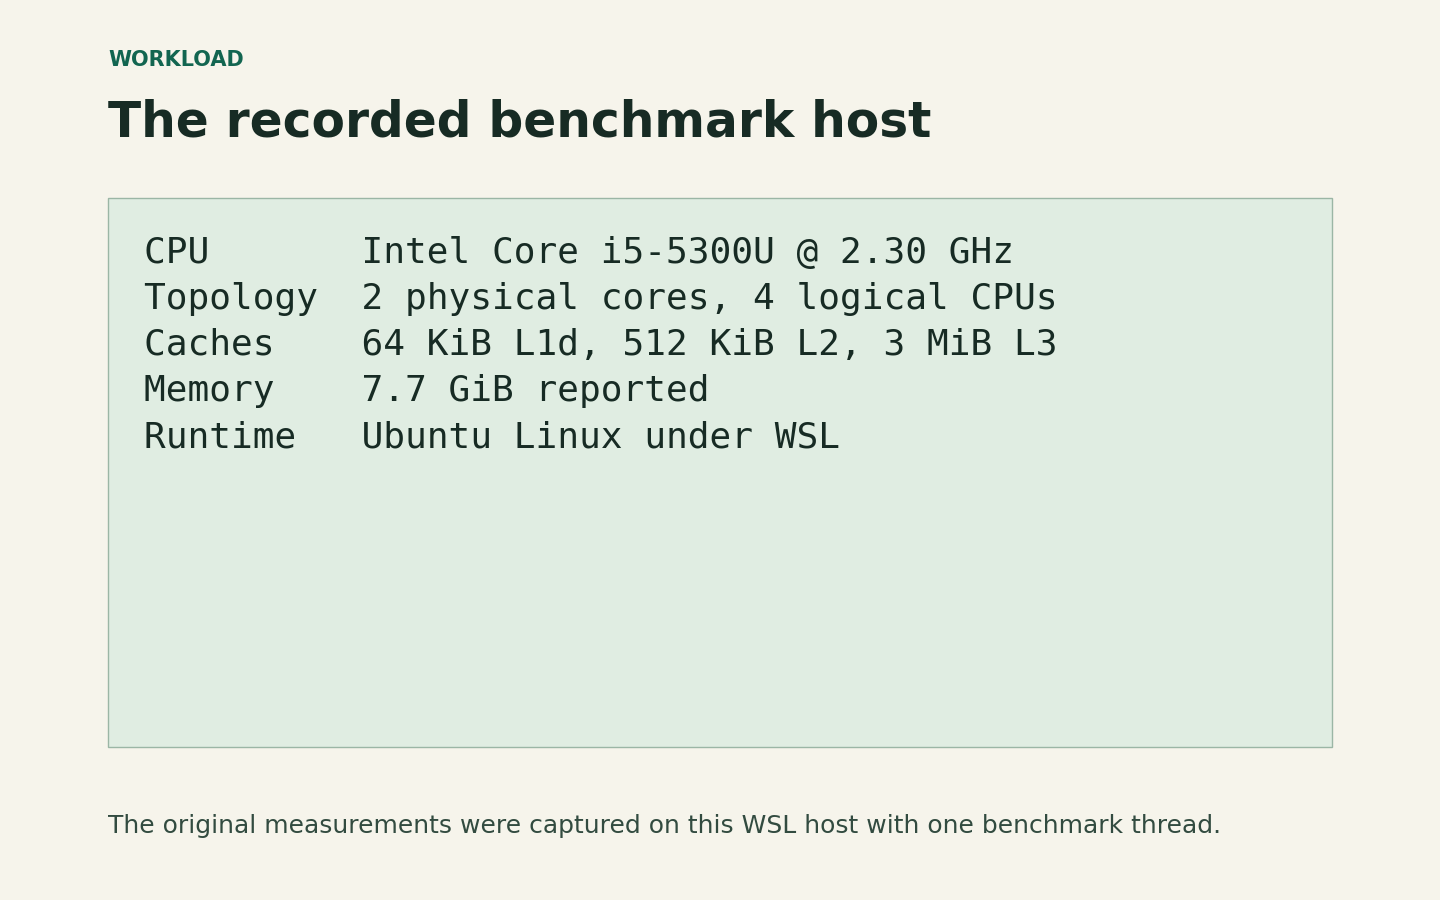
The original December 2025 logs used one rank and one thread on Ubuntu under WSL on an Intel Core i5-5300U. Both logs show VALID and the same raw SpMV operation count. The selected pair shows a small improvement in the kernel and a lower overall score. Multigrid is the largest component in both logs and took longer in the unrolled run.
Comparing fresh reports
The comparison tool checks that the reports are valid and agree on grid dimensions, ranks, threads, nonzeros and raw SpMV work. It reports the median and observed range for each metric. Run both variants with the same compiler flags and input, and alternate which runs first when collecting repeats.
python tools/compare_runs.py --baseline path/to/baseline.txt --candidate path/to/unrolled.txtCurrent local correctness checks
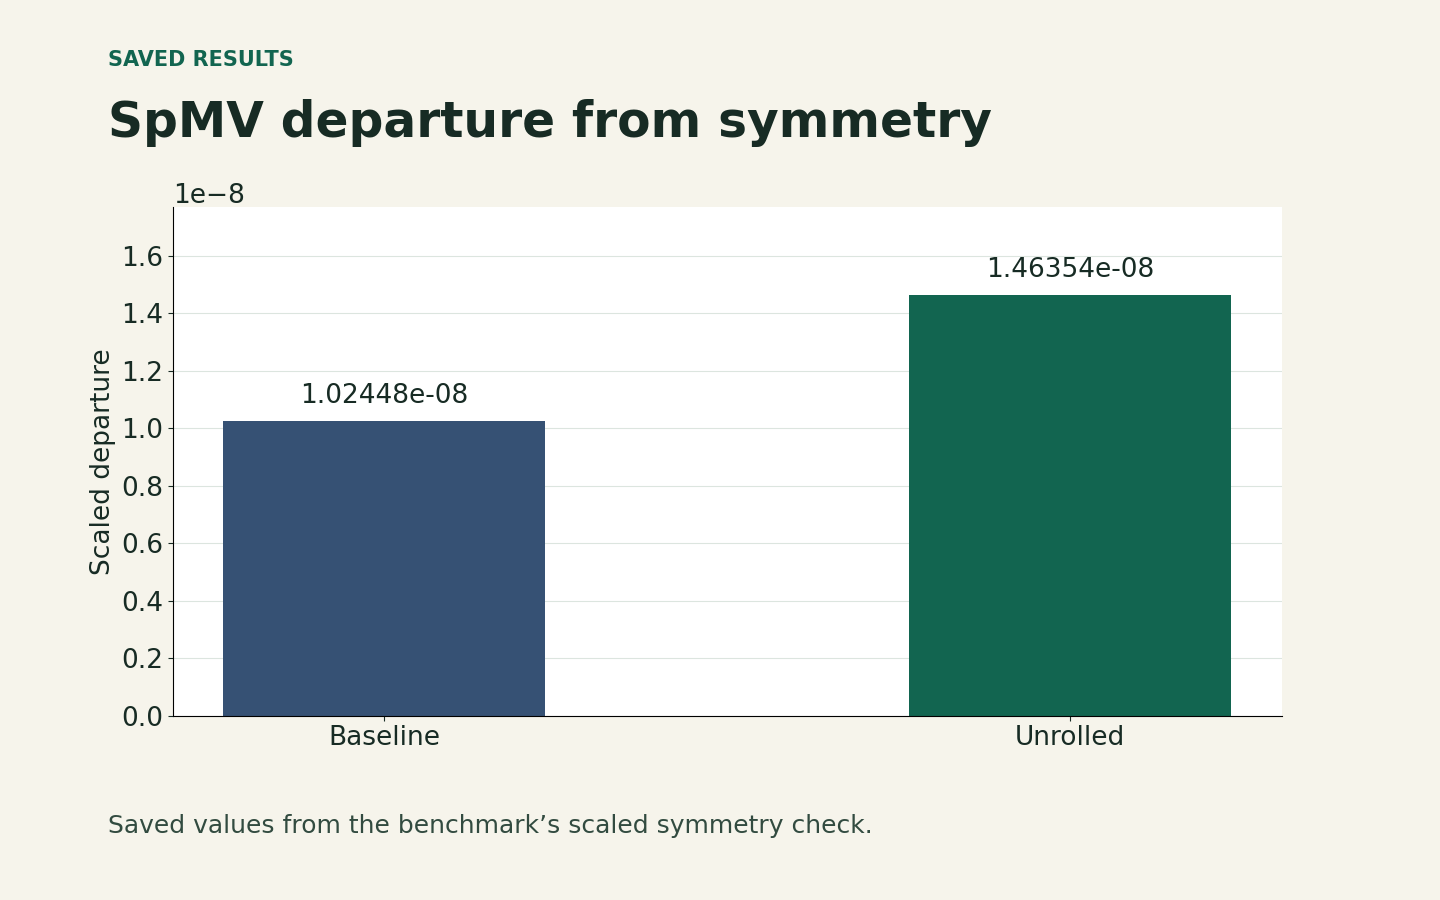
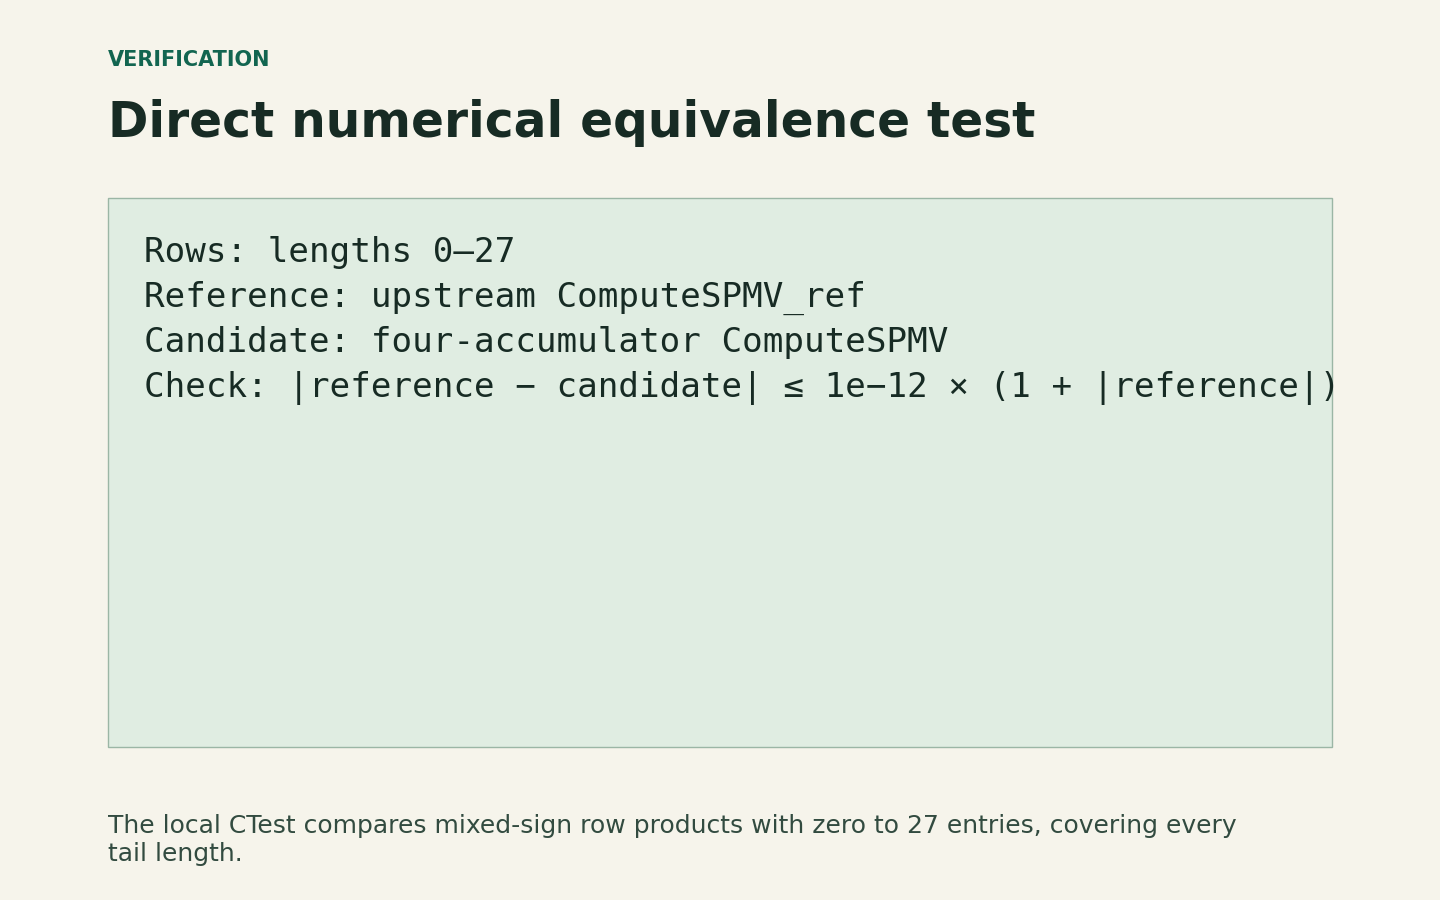
The current Windows Release build was checked independently. CTest compared mixed-sign row products over 0–27 entries with the upstream reference and measured a maximum absolute difference of 3.10862e−15. Both current binaries reported VALID on 16³, passing convergence, symmetry, iteration-count, and reproducibility checks. Those short runs verify execution and correctness.
Limitations
The archived performance comparison consists of one selected pair on one machine. It has no repeated-run variance estimate, and the short duration does not qualify for an official HPCG submission. The current Windows checks use a smaller problem, a different timer and toolchain, and a corrected entry point. MPI, OpenMP, and 104³ performance of the maintained build were outside those checks.
Screenshot Gallery
24 figures